Google Cloud Professional Data Engineer & Cloud Architect

Hi, I'm

Jorge Lira

Mid-level Data Engineer · Maceió, Brazil — Remote

I build reliable, cost-aware data pipelines on Google Cloud, from ingestion to analytics-ready data in BigQuery.

2.6 years of data engineering at Leega, a data consultancy, delivering GCP projects for enterprise clients. Before that, 3 years as a software developer.

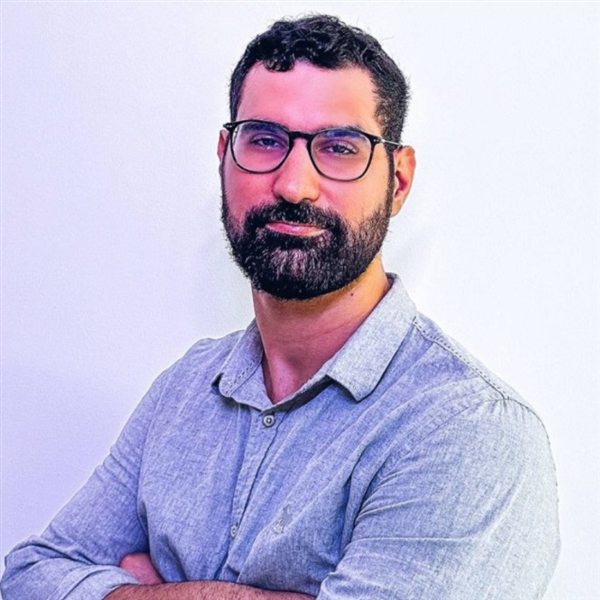
Portrait of Jorge Lira
2.6
years in data engineering
6
cloud & data certifications
449M
records migrated to GCP

~/experience

Experience

Client engagements at a data consultancy. Client names and code are confidential, so each case covers the problem, the approach and the outcome.

Data Engineer · Leega

May 2024 – present · Remote · Data consultancy: data engineering and architecture on GCP for enterprise clients

ERP software · 2026 – present

ERP data integration and pipeline operations

  • 150+ tables
  • 8 tenants
  • Tens of millions of records affected by the failure

Problem

Records deleted in the ERP (Oracle) stayed active in BigQuery — a critical replication failure that affected accounting figures.

Solution

As the sole technical owner of the integration, traced the root cause to a trigger condition that blocked the capture of logical deletes, and defined a business-key deduplication standard that handles re-ingestions, replacing a criterion that produced duplicates.

Result

Failure diagnosed and resolved, with an estimated impact of tens of millions of records, and re-ingestions made safe across 150+ tables in 8 tenants.

  • Operate and evolve the ingestion pipelines: view modeling, deduplication of versioned records and analytical queries for reporting
  • Optimized BigQuery queries, significantly reducing data processed per run through filter tuning, partitioning and column selection
  • Technical interface with the ERP, database and connector teams; support for client analysts on queries and the data model
ERP Oracle Trigger capture Data platform BigQuery logical deletes not captured business-key dedup

Retail · 2026

BigQuery FinOps and query optimization

  • 90%+ less time and data processed
  • ~83% lower monthly cost on mapped routines
  • ~US$ 112.4k projected yearly savings

Problem

High BigQuery costs: the largest offenders in slot consumption and data volume had to be found and fixed.

Solution

Led the technical mapping and diagnosis in a team of 4 engineers, then refactored the critical queries applying SQL and data architecture best practices.

Result

90%+ gains in execution time and data processed, ~83% lower monthly cost for the mapped routines and ~US$ 112.4k/year in projected savings.

BigQuery slots · data volume FinOps diagnosis · team of 4 Refactoring queries ~83% monthly cost

Telecom · 2025

Teradata and Oracle migration to GCP

  • 449M records migrated
  • 24h → 12h load window

Problem

Move 449 million records from Teradata and Oracle to Google Cloud.

Solution

Python DAGs in Apache Airflow for orchestration, processing on Dataflow and final load into BigQuery, plus Cloud Logging and a log sink for monitoring and delivering logs to the client.

Result

The load window dropped from 24 hours to 12 hours.

Airflow · Cloud Logging Teradata Oracle Dataflow BigQuery 449M 24h → 12h

Internal · 2025

RAG chatbot for résumé analysis

Proof of concept

Problem

Screen candidates by asking questions about résumés in natural language.

Solution

RAG architecture with Vertex AI, Gemini models and Cloud Storage for document-grounded answers, extracting and structuring skills and experience from the résumés.

Result

Technical feasibility validated for candidate screening.

User questions VERTEX AI Gemini RAG Cloud Storage résumés context

Full Stack Developer · Freelance

Aug 2023 – May 2024 · Maceió, Brazil

Built applications and websites with Python/Django, Django REST Framework, React, Node.js and PostgreSQL, including front-end integration with APIs.

Full Stack Developer (Delphi) · Grupo In4

Aug 2021 – Jul 2023 · Maceió, Brazil

Front-end and back-end development in Delphi for corporate systems in production, with ticket management and prioritization, version control (Git) and team collaboration.

~/projects

Projects

Personal projects, from a finished data platform on GCP to what I'm building right now.

Fuel Data Platform (ANP)

Medallion data platform on GCP for Brazil's public fuel data, published by the National Petroleum Agency (ANP).

Completed
ANP API Dataflow Apache Beam CLOUD STORAGE · PARQUET Bronze raw Silver cleaned Gold metrics Dataproc Spark · ephemeral BigQuery external tables & views Looker Studio Cloud Composer Airflow
A Dataflow (Apache Beam) job pages through the ANP API and lands Parquet files in Cloud Storage (Bronze). Spark on Dataproc cleans and normalizes the data (Silver), and aggregated metrics are built on top (Gold): market share by distributor, capacity by state and the evolution of the station base. BigQuery exposes the layers through external tables and views for Looker Studio dashboards. Cloud Composer (Airflow) orchestrates the pipeline.

Problem

Centralize Brazil's public fuel data with reliable ingestion, scalable processing and analytics-ready data, while keeping cost and quality under control.

Highlights

  • Hive-style partitioning (uf/data_obtencao) for partition pruning in BigQuery
  • Ephemeral Dataproc clusters to keep processing cost down
  • Isolated service accounts
  • Executive dashboard and a dashboard focused on Alagoas
  • Python
  • Apache Beam
  • PySpark
  • Dataproc
  • Cloud Storage
  • Cloud Composer
  • BigQuery
  • Looker Studio
  • Docker
View code on GitHub

Clairemind — personal AI assistant on WhatsApp

Manages calendar, tasks, lists and reminders, understands voice messages and negotiates meetings with other people, all in natural language. Used daily in real life.

In progress
  • ~41% LLM cost saved with prompt caching
  • 5/5 adversarial privacy and jailbreak tests passed
  • Daily backups with validated restores
WhatsApp text · voice DOCKER COMPOSE · GCP VM Evolution API Postgres · Redis n8n webhook Brain · Node.js ports + state machines SQLite Claude Haiku 4.5 tools · Whisper Google Calendar OAuth2
Messages (text or voice, transcribed with Whisper) arrive from WhatsApp through Evolution API and an n8n webhook to the Node.js brain. Claude can only act through fixed tools ("ports"): the code executes them, writes the confirmation text and routes the result to Google Calendar or SQLite.

Problem

LLM assistants tend to claim actions they never performed and to invent missing data — names, phone numbers, times. For a secretary that edits your calendar and writes to other people, that is unacceptable.

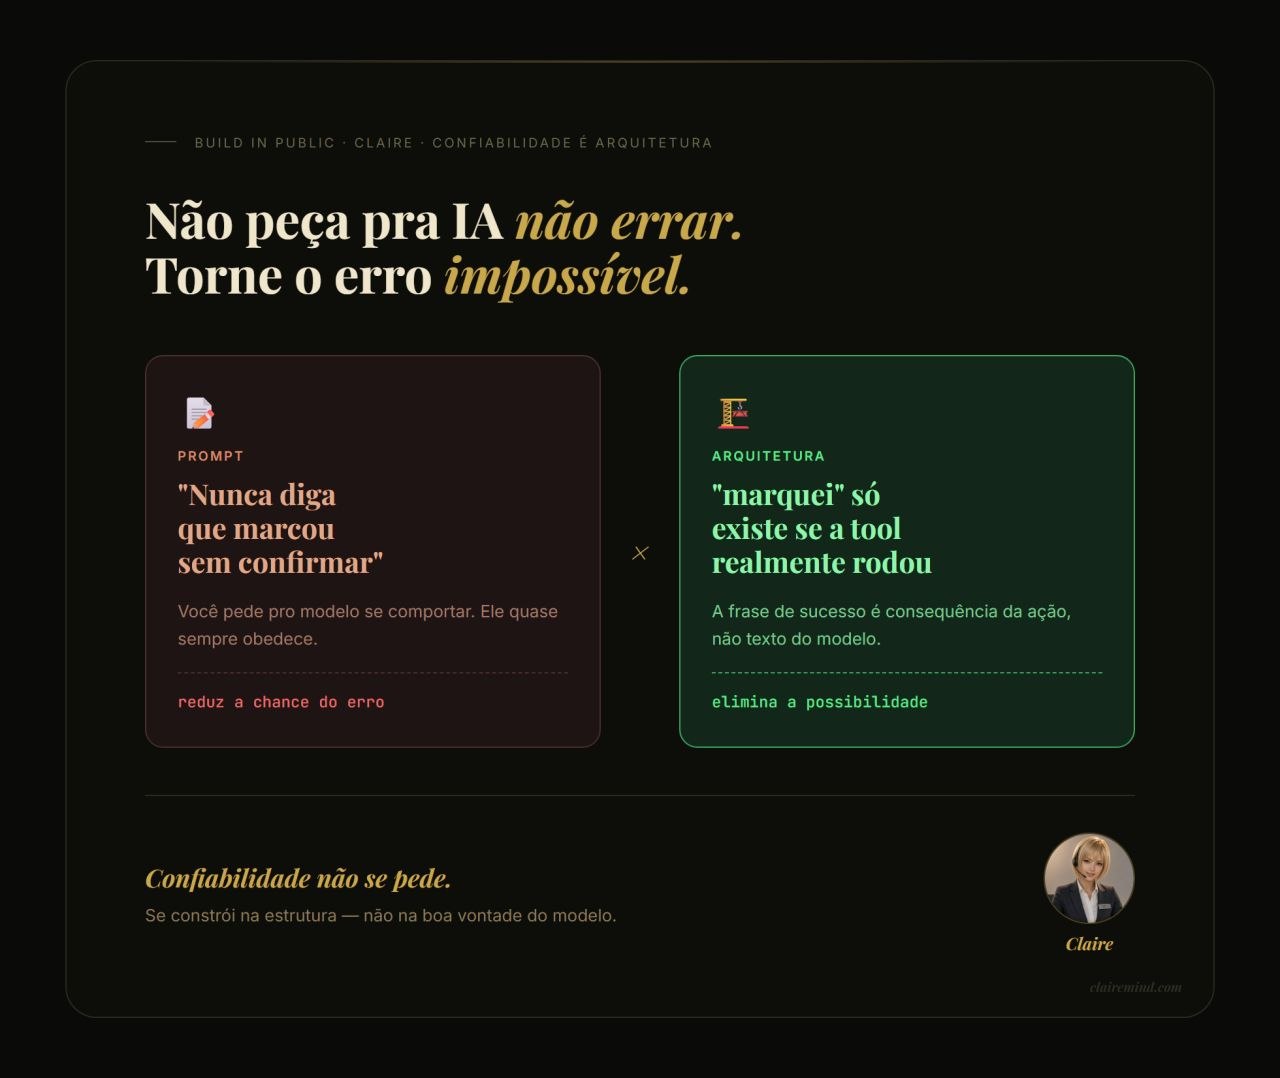
LinkedIn build-in-public post: "Don't ask the AI not to fail. Make the failure impossible." A prompt only reduces the chance of the error; the architecture removes the possibility.
From the build-in-public series on LinkedIn: "Don't ask the AI not to fail. Make the failure impossible."

Engineering decisions

  • Harness over prompt: the model decides what to do; the code controls how it comes out. Confirmations and agenda dates are generated by code, so the assistant never states an action it didn't execute or a date it made up.
  • Structural fixes beat prompt fixes: required schema fields pushed the model to guess missing data. Making them optional and letting the code pick the default fixed it; "don't invent" in the prompt didn't.
  • The model labels, the code routes: one entry tool classifies task vs. appointment, and routing to SQLite or Google Calendar is deterministic.
  • Safe by construction: messages to third parties only go to saved contacts, so an invented phone number can't be used.
  • Concurrency: a race condition in third-party relays fixed with an atomic claim, validated with parallel requests.
  • Async meeting negotiation as explicit state machines, recurring events as a single RRULE series, and multi-tenant isolation with encrypted OAuth2 refresh tokens.

Running in production

  • GCP VM behind nginx with SSL and Cloudflare DNS; SSH only through IAP, with port 22 closed to the internet
  • Daily SQLite and n8n backups to Cloud Storage with lifecycle rules; restores validated, including during a real incident
  • API token, input validation, rate limits per IP and per client, and a daily cost cap

Lakehouse Factory

An animated, interactive data pipeline drawn as a warehouse: events travel from an API through Bronze, Silver and Gold to the dashboard — and you can break it on purpose.

Interactive
orders-api 2,400 events/s Pub/Sub Dataflow scales out Bronze as received Silver dbt · dedup Gold dbt tests Looker Vertex AI API incident: 6× volume, amount as text quarantine → replay
A simulated pipeline at the scale of a large operation (about half a billion rows a day). Dataflow writes everything to Bronze as it arrives. In Silver, dbt removes duplicates (Pub/Sub can deliver the same message twice) and test orders, about 3% of rows. dbt tests decide what reaches Gold, which feeds Looker, Vertex AI and an API.

Problem

Many people use data every day without seeing the path it takes — or what happens to it when something breaks along the way.

"Simulate incident"

  • A deploy sends 6× the volume and turns amount from a number into text
  • The queue grows and Dataflow scales out
  • Bad batches go to quarantine before Gold, and Looker flags that the data is incomplete
  • Replay recovers everything with no batch lost
  • A detail anyone who watches dashboards knows: the queue drains before the SLA turns green again, because late batches stay in the window for a while

Currently building

dbt project on BigQuery

Analytics engineering on BigQuery's public thelook_ecommerce dataset, built alongside the ALL-IN-ONE dbt Bootcamp.

In progress
GitHub Actions · dbt build BIGQUERY · DBT CORE 1.12 thelook_ecommerce sources · freshness staging 4 models intermediate 2 models marts 4 models 1 incremental snapshot · SCD2 data tests on every layer
Planned structure, being built now: staging, intermediate and mart models with an incremental fct_order_items, a Type 2 snapshot for history, data tests and source freshness, and dbt build in CI.

Goal

Practice analytics engineering end to end on realistic e-commerce data (users, orders, order items and products): layered models, tests, incremental loads, history tracking and CI.

Scope

  • 4 staging, 2 intermediate and 4 mart models
  • Incremental fact table (fct_order_items, MERGE) and an SCD Type 2 snapshot
  • Data tests and source freshness checks
  • Pinned dbt Core 1.12 with dbt build in GitHub Actions

~/skills

Skills

Google Cloud

  • BigQuery
  • Dataflow / Apache Beam
  • Cloud Composer / Airflow
  • Cloud Storage
  • Dataproc
  • Cloud Logging
  • Vertex AI

Other platforms

  • Databricks
  • AWS

Languages & processing

  • Python
  • SQL
  • PySpark
  • JavaScript

Pipelines

  • Apache Airflow
  • Dataflow
  • ETL / ELT
  • ERP data integration
  • API connectors (Zendesk, Jira)

Data modeling & architecture

  • Relational & dimensional modeling
  • Medallion architecture
  • Data Lake
  • Data Warehouse
  • Data Mart
  • Data quality & governance
  • FinOps
  • dbt learning

Operations

  • Incident resolution
  • Root cause analysis
  • Monitoring & logging
  • Technical documentation

BI

  • Looker Studio
  • Power BI

AI

  • RAG (Vertex AI, Gemini)
  • LLM function calling

Tools

  • Git
  • Docker
  • Jupyter
  • Jira

~/certifications

Certifications

~/about

About

I'm a data engineer based in Maceió, Brazil, working remotely. I spent 3 years as a software developer (Python/Django, Delphi) before moving into data engineering, where I've spent the last 2.6 years at Leega building GCP solutions for enterprise clients.

Outside client work I keep building: a data platform for public fuel data, a WhatsApp AI assistant I use every day and an animated simulation that explains how a pipeline behaves during an incident. Right now I'm deepening my analytics engineering skills with a dbt project on BigQuery.

I hold a degree in Civil Engineering from Mackenzie Presbyterian University. Portuguese is my native language, and my English is advanced, used at work for reading, writing, meetings and technical documentation.

~/contact

Let's talk

Want to talk about data, pipelines or a project? The best way to reach me is by email or LinkedIn.

jorgelira542502@gmail.com